
Imagine a customer visiting your website during a busy sales event, only to find that the page refuses to load. Frustrating, isn’t it? Reliable web applications don’t happen by accident. They are built with careful planning, resilient infrastructure, thoughtful coding, and continuous monitoring to keep services running smoothly even when unexpected problems arise.
Businesses increasingly depend on digital platforms to manage customers, transactions, and daily operations. A reliable Website Development Company in Jaipur understands that building a successful web application involves more than creating attractive interfaces. It also requires designing systems that can handle traffic fluctuations, recover from failures, and deliver consistent performance.
1. Design for Failure, Not Just Success
One of the biggest lessons in modern web development is that failures are inevitable. Servers may crash, databases may become temporarily unavailable, network connections may weaken, and software updates may introduce unexpected issues. Highly available applications are designed with these possibilities in mind rather than assuming everything will work perfectly.
Instead of relying on a single server, developers distribute application workloads across multiple instances. If one server stops responding, another can continue handling requests. This approach reduces the risk of a single point of failure bringing down the entire application.
Important architectural practices include:
- Redundant infrastructure: Maintain multiple application instances so a single failure doesn’t interrupt the entire service.
- Load balancing: Distribute incoming traffic across healthy servers to prevent overload.
- Fault isolation: Separate critical services so problems in one component don’t affect everything else.
- Graceful degradation: Allow essential features to remain available even when some non-critical functionality fails.
These practices make applications more resilient and give developers greater control over how systems respond to unexpected disruptions.
2. Build a Scalable Infrastructure
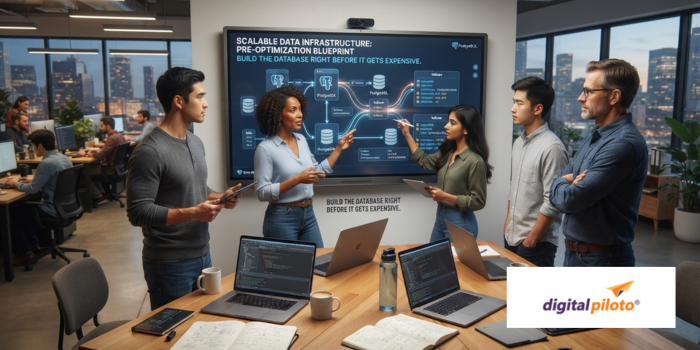
Traffic rarely follows a predictable pattern. A web application might handle a few hundred visitors on an ordinary day and suddenly receive thousands during a product launch. Infrastructure that works comfortably under normal conditions may struggle when demand increases.
Scalability helps applications adapt to changing workloads. Horizontal scaling involves adding more servers or instances, while vertical scaling increases the resources available to an existing server. For many modern applications, horizontal scaling offers flexibility and helps improve resilience when combined with appropriate architecture.
Cloud platforms, containerisation, and automated deployment systems can make scaling more manageable. However, adding servers alone won’t solve every performance problem. Developers also need to consider database bottlenecks, inefficient queries, memory usage, and external service dependencies.
The Google Site Reliability Engineering book offers valuable guidance on reliability engineering, operational practices, and designing systems that balance reliability with development speed.
3. Protect Database Reliability and Performance
Even the most carefully designed application can become unreliable when its database struggles. Databases often handle the most valuable information in an application, from customer accounts and payment records to product inventories and business transactions.
Developers should make database performance and availability a priority from the beginning. Caching frequently requested data, optimising queries, managing connection pools, and using appropriate indexing can reduce unnecessary workload.
Database reliability strategies worth implementing:
- Regular backups: Create scheduled backups and verify that restoration procedures actually work.
- Replication: Maintain database replicas to support availability and, depending on the configuration, recovery or read scaling.
- Query optimisation: Identify slow queries and improve execution efficiency.
- Connection management: Prevent excessive database connections from overwhelming the system.
- Recovery planning: Define recovery objectives and prepare for data loss or infrastructure failures.
These measures help protect data while supporting a more responsive application experience.
4. Monitor Applications and Automate Recovery
Reliability isn’t something developers can simply assume after deployment. Applications need continuous monitoring to reveal problems before users begin reporting them. Useful monitoring systems track response times, error rates, resource consumption, availability, and unusual behaviour.
Automated health checks can identify unhealthy application instances and prevent them from receiving additional traffic. Alerting systems notify engineers when performance deteriorates, while automated deployment and rollback mechanisms help reduce the risks associated with software updates.
Businesses working with a Website Development Agency in Jaipur can benefit from incorporating monitoring, deployment automation, and recovery planning into their development lifecycle rather than treating reliability as an afterthought.
5. Prioritise Security and Continuous Improvement
Security problems can affect application availability just as much as infrastructure failures. A compromised server, malicious traffic, or vulnerable dependency may disrupt services and damage customer trust. Strong security practices therefore form an important part of reliable web application development.
Keep software dependencies updated, enforce secure authentication, use HTTPS, restrict access to sensitive resources, and protect applications against common vulnerabilities. Regular security reviews and testing help uncover weaknesses before they become serious problems.
An experienced India Web Design Company with a strong development approach can help businesses combine secure coding, responsive design, performance optimisation, and scalable architecture into a dependable digital solution.
Frequently Asked Questions
What is a highly available web application?
A highly available web application is designed to remain accessible and operational despite infrastructure failures, traffic fluctuations, or other disruptions through redundancy, monitoring, and recovery mechanisms.
How can developers improve web application availability?
Developers can improve availability by implementing load balancing, redundant servers, database replication, monitoring, automated recovery, secure infrastructure, and regular testing.
What is the difference between scalability and high availability?
Scalability refers to a system’s ability to handle increasing workloads, while high availability focuses on keeping services accessible. They often work together but solve different problems.
Why is monitoring important for web applications?
Monitoring helps developers identify performance issues, errors, infrastructure problems, and unusual activity. It enables faster troubleshooting and helps prevent minor issues from becoming major disruptions.
Final Thoughts
Highly available web applications are built through a combination of smart architecture, reliable infrastructure, efficient databases, proactive monitoring, and strong security practices. There isn’t a single secret that guarantees uninterrupted service. Instead, reliability comes from anticipating failure, learning from experience, and continuously improving the system. When these principles become part of development culture, applications are better prepared to grow without sacrificing user trust.
Blog Development Credits
This article was conceived by Amlan Maiti, enriched through advanced AI-assisted research, and professionally refined for technical accuracy, readability, and SEO by Digital Piloto Private Limited.
Audio – Listen Here